Product overview
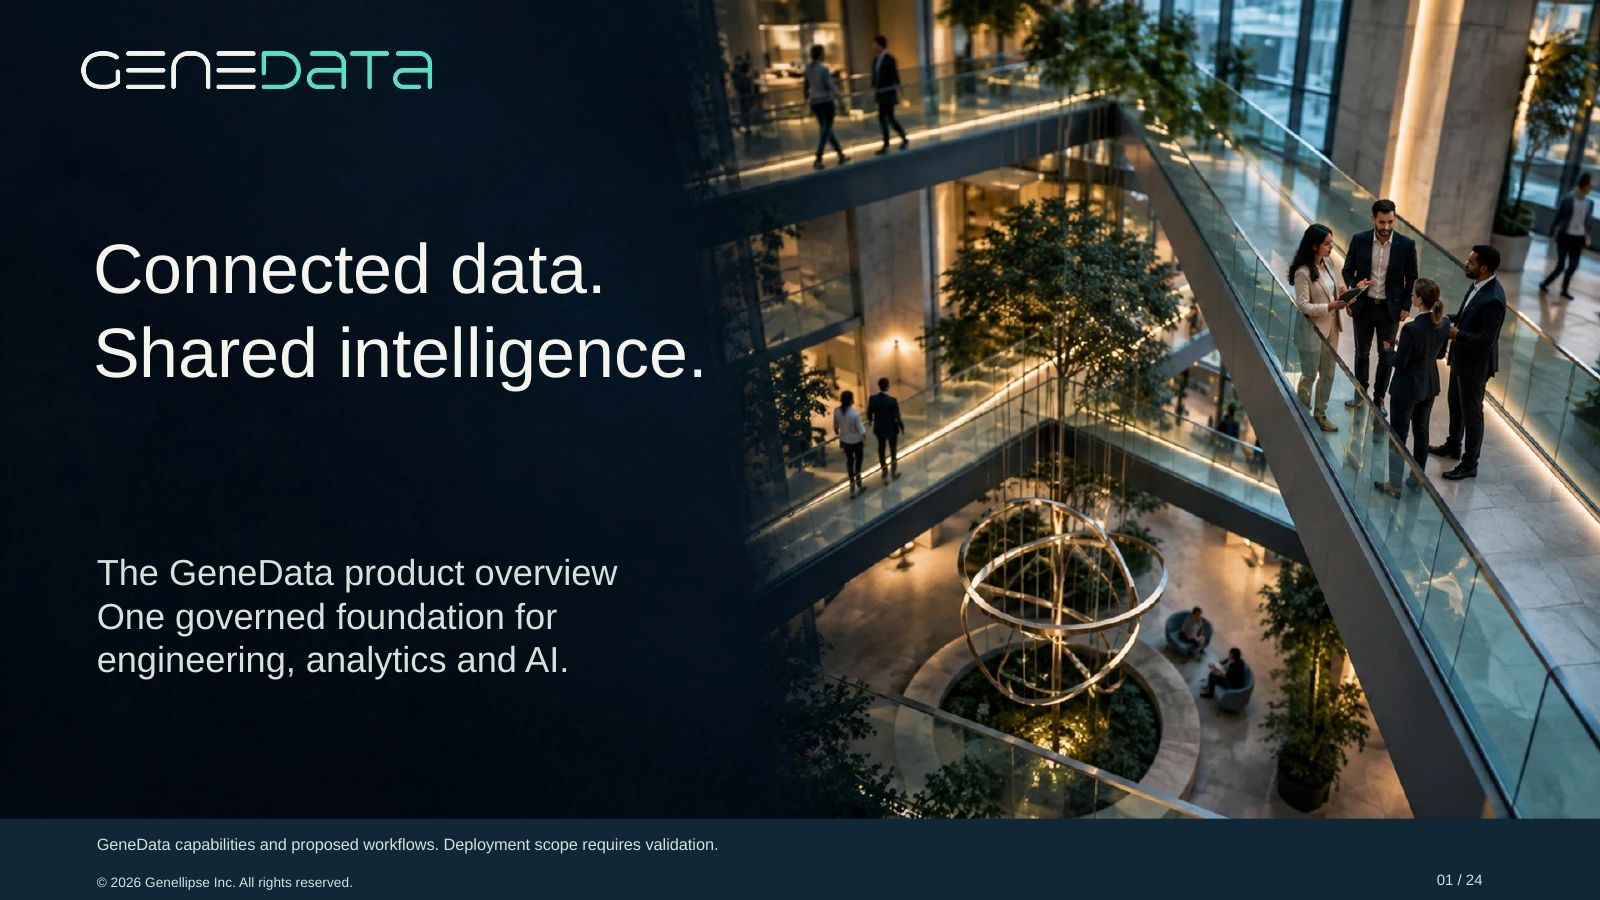
One governed foundation for data engineering, analytics and AI.
24 slides · English · Interactive scenarios
View presentation
01 / Overview
Unify data engineering, warehousing, analytics, and AI on an enterprise data platform with governance built into every workflow.
Genellipse plans a focused MVP within 6 weeks. Agree the outcome, interfaces, access, client reviewers, and acceptance criteria at the start. Use the delivered evidence to decide the next stage.
ILLUSTRATIVE WORKFLOW
Connect & engineer
Analyze & build AI
Govern & operate
Confirm the capabilities and configuration appropriate to your requirements.
GENEDATA · PRODUCT AND ROLE SHOWCASES
Explore the product overview and five detailed role showcases. Follow complex data from ingestion and modelling to analytics, AI and reliable operations, with security at every handoff.
Explore GeneData capabilitiesOne governed foundation for data engineering, analytics and AI.
24 slides · English · Interactive scenarios
View presentation
Reliable pipelines for complex sources, with data contracts, recovery and shared lineage.
24 slides · English · Interactive scenarios
View presentation
Trusted metrics and explainable decisions, built on shared definitions and source evidence.
23 slides · English · Interactive scenarios
View presentation
Reproducible models, rigorous evaluation and controlled business impact.
24 slides · English · Interactive scenarios
View presentation
Shared models, historical context and dependable data contracts that support business change.
23 slides · English · Interactive scenarios
View presentation
Dependable data services through safe modernisation, workload control and tested recovery.
25 slides · English · Interactive scenarios
View presentationGeneData
GeneData covers the enterprise data lifecycle: connect sources, build and run pipelines, query a warehouse, define shared metrics, and support data science and AI. Catalog, lineage, access, and operational controls keep the work connected as it passes between teams.
EXPLORE GENEDATA
GeneData connects the work of data engineers, analysts, data scientists, and business teams. Bring pipelines, SQL, business intelligence, machine learning, and shared knowledge together, with a common catalog, lineage, access controls, and audit history. Connect the systems you already use and expand from your first use case.
Connect databases, cloud services, applications, and files. Build batch and streaming pipelines, manage data quality, and query governed data through a SQL warehouse.
Work with shared metrics, dashboards, and reports. Develop models and AI workflows with tools for evaluation, approvals, and operational oversight.
Discover data and business knowledge in a shared catalog. Follow lineage, manage permissions, and keep ownership, policies, and evidence connected to the work.
INSIDE GENEDATA
Explore the capabilities behind the platform, the work each supports, and the details to examine with your team.
Connect sources and build batch, streaming, and change-data-capture pipelines. Visual design and code-based transformation share an execution graph, with dependencies and quality assertions attached to the work.
Cortex SQL brings analytical querying to a warehouse that separates storage from compute. The platform describes support for Iceberg, Delta, and Parquet so data can be used across compatible tools.
Bring technical metadata, business definitions, ownership, and lineage into a shared discovery layer. Give teams a way to understand what a dataset means and how an upstream change may affect its consumers.
Build analysis, dashboards, recurring reports, and briefings around shared metrics. Connect the result to the definitions and sources that support it so users can investigate a change in the numbers.
Use the data foundation for analytical models, experiments, and AI workflows. Connect model and agent activity with the relevant datasets, evaluation expectations, and review responsibilities.
Manage access, ownership, approvals, and operational evidence across the data lifecycle. Review freshness, quality, workload health, usage, and cost alongside the business uses they support.
A WORKFLOW IN PRACTICE
An illustrative example: a team needs a repeatable operational report and a trusted dataset for further analysis. Follow both the data and its ownership through the workflow.
Select the operational sources, identify the owners, and agree the business definitions and access requirements for the dataset.
Create the ingestion and transformation pipeline. Attach quality rules and establish how failed checks or late inputs will be handled.
Publish the governed output for queries, dashboards, or model work. Keep metric definitions and lineage available to the people using the result.
Monitor freshness, pipeline health, access, and cost. Review the impact of source or logic changes before extending the data product to new uses.
YOUR EXISTING ENVIRONMENT
GeneData is positioned to connect existing databases, applications, cloud platforms, files, and event streams. Begin with the sources and consumers required for one data product. Assess connector fit, network access, source load, table formats, and ownership before deciding what to retain, connect, or migrate.
FROM CAPABILITY TO APPLICATION
When pipelines, reporting, models, and governance live in separate tools, teams spend time reconciling definitions and reconstructing how an answer was produced. GeneData brings these activities into a shared environment so data can move from source to business use with its ownership and context intact.
Bring operational sources into a defined pipeline, apply quality checks, and publish a dataset with an owner and a documented meaning. Give downstream analysts and model builders a common starting point.
Create analysis and dashboards around shared business definitions. Follow lineage when an input changes so the team can understand the effect on a metric, report, or decision.
Connect governed datasets and business knowledge to model and agent workflows. Keep access, evaluation, and review requirements in view as a use case moves beyond experimentation.
PLAN A USEFUL EVALUATION
Bring a representative example, the people who own it, and the requirements it must meet. Review the whole path from input to output, including exceptions and handoffs.
EVALUATE WITH CONFIDENCE
Genellipse plans a focused MVP within 6 weeks. Agree the outcome, interfaces, authorized access, client reviewers, and acceptance criteria before delivery begins.
COMMON QUESTIONS
Explore the scope, practical considerations, and a useful starting point for your team.
GeneData is an enterprise data and AI platform. It brings data engineering, a SQL warehouse, a shared catalog, business intelligence, data science, and governed AI workflows together. It serves the broader data lifecycle, from connecting sources to using information in operational decisions.
The platform is designed to connect existing databases, applications, files, cloud environments, and data platforms. A useful starting point is one source-to-decision workflow. Migration scope and any systems to retain should be agreed during architecture planning.
Choose a recurring business question whose data is currently difficult to assemble or trust. Trace the required sources, define the output, identify who can access it, and agree how you will assess data freshness, quality, and usability.
TAKE A CLOSER LOOK
See the product, explore its capabilities, and find your next step.